Best Strategies for Scaling AI Projects Within a Team
Scaling an AI project from solo work to a functioning team is where most companies hit a wall. The code works, the model runs, but suddenly you have conflicting changes, unclear ownership, and no one's sure who's responsible when something breaks. This is the moment teams either establish real discipline or watch their productivity collapse. The strategies here aren't about process for process' sake, they're about keeping a team moving fast while maintaining control.

Scaling an AI project from solo work to a functioning team is where most companies hit a wall. The code works, the model runs, but suddenly you have conflicting changes, unclear ownership, and no one's sure who's responsible when something breaks. This is the moment teams either establish real discipline or watch their productivity collapse. The strategies here aren't about process for process' sake, they're about keeping a team moving fast while maintaining control.
Photo by Antoni Shkraba from Pexels
TL;DR:- Team collaboration requires shared tooling, clear communication protocols, and defined code ownership.
- Effective AI team scaling depends on collaborative tools like GitHub/GitLab, feature branching, and asynchronous documentation.
- Integration of AI into existing workflows requires careful planning around validation gates, review processes, and rollback strategies.
- Leadership must establish guardrails early, shared standards for AI output, security gates, and team norms prevent chaos at scale.
Scaling an AI project on a single engineer looks entirely different from scaling it across a team of five, ten, or fifty. One person can hold the whole system in their head. A team cannot. The moment you add a second engineer, you need version control discipline. The third person demands code review standards. By the fifth, you're facing integration conflicts, unclear ownership, and the first serious "this broke in production."
The difference between a team that scales AI effectively and one that drowns is not talent. It's structure. It's the unglamorous work of establishing shared tools, communication rituals, and clear boundaries around what AI output is acceptable to ship. This is the job of a technical lead or CTO.
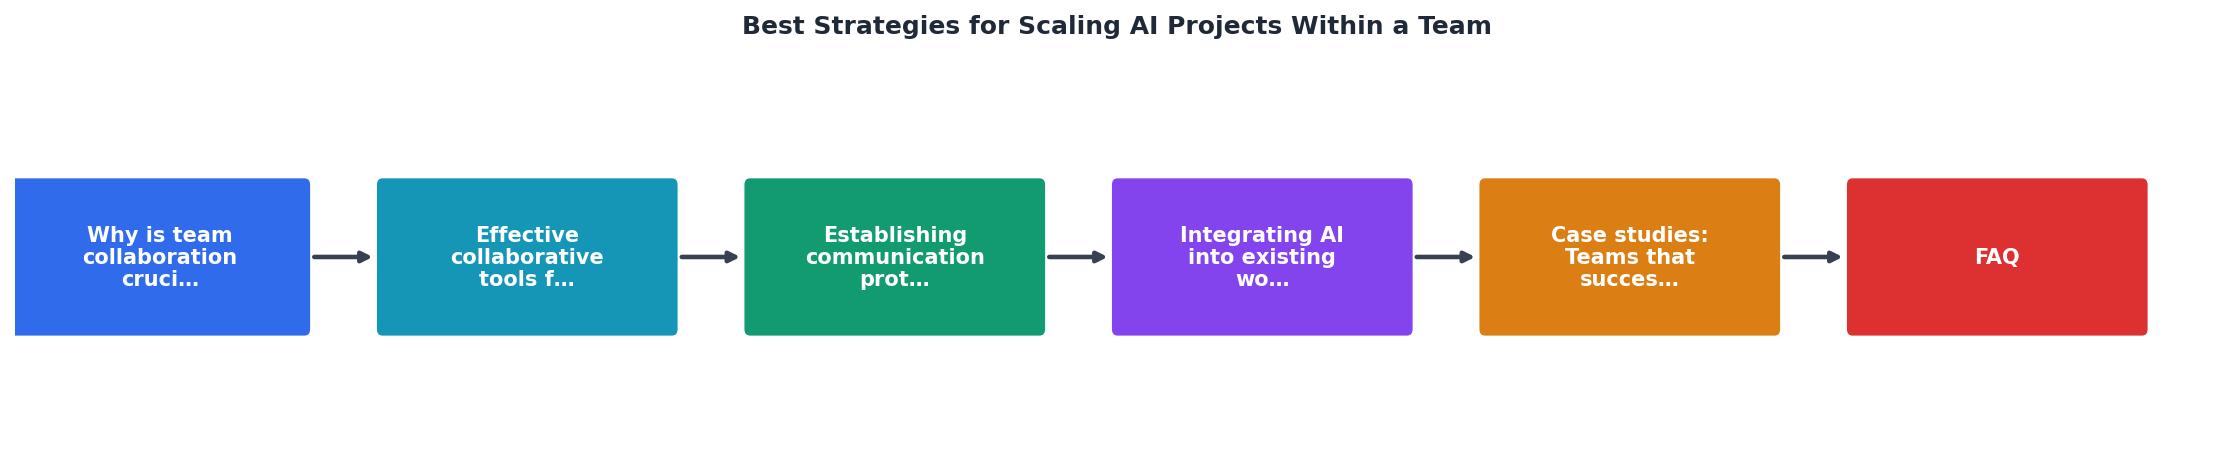
Why Team Collaboration Matters
Team collaboration in AI projects is not about feeling connected. It's about preventing the same work from being done twice, avoiding contradictory changes that cancel each other out, and catching breaks before they hit production.
When a solo engineer builds an AI feature, they own the entire stack: model training, feature branch, code review (mental checklist), testing, and deployment. When a team builds it, those steps fragment across people. Without structure, you get:
- Duplicate effort: Engineer A trains a model. Engineer B trains another one independently. Both land, one overwrites the other.
- Conflicting changes: Model training happens on separate branches. Merging them breaks the inference pipeline.
- Unclear ownership: No one knows who's responsible for retraining the model next week.
- Silent failures: A change that breaks data validation slips past review because reviewers didn't know to check it.
Clear collaboration prevents all of these. It doesn't require heavy process. It requires the right tools, explicit agreements, and consistent enforcement.
Choose Your Collaborative Tools
The tooling layer determines what's possible. Pick the wrong tools and your team spends energy fighting the system. Pick the right ones and they feel invisible.
Version control (Git, GitHub, GitLab) is non-negotiable. Every AI project touches code, data pipelines, model configs, and training scripts. All of it goes in Git. Some teams hesitate on this, "models are too big for Git", but that's a misunderstanding. Models go in object storage (S3, GCS). Model references, training configs, and code go in Git. This is table stakes.
Issue tracking (Jira, GitHub Issues, Linear) creates the single source of truth for what's being worked on. Without it, one engineer thinks a task is done while another thinks it's not started. Use issues to track:- Feature development
- Model training runs
- Data pipeline changes
- Production incidents
- How the model pipeline works
- Deployment procedures
- On-call runbooks
- Architecture decisions and why they were made
- Code linting and format checks
- Unit tests for preprocessing and feature engineering
- Integration tests with sample data
- Model validation (performance on test set, schema checks)
- Data quality checks before retraining
Tool Selection Checklist
- Git-backed: Does it integrate with your version control system?
- Audit trail: Can you see who changed what and when?
- Permissions model: Can you restrict who can merge code or deploy models?
- API access: Can you automate workflows with scripts?
Establish Communication Protocols
Tools don't communicate by themselves. You need protocols, explicit agreements about when and how information flows.
Code review is the primary gate. Every change to production code or model logic should go through review before merge. For AI projects, reviewers should specifically check:- Does the change align with the model's intended behavior?
- Are there data assumptions that could break in production?
- Is the change tested with realistic data?
- Does it follow the team's security standards?
Merge discipline prevents conflicting changes. Use feature branches. Require passing CI before merge. Require at least one approval. Delete the branch after merge. This sounds mechanical, but it scales. A team of two can get away with pushing to main. A team of ten will have constant conflicts.
Deployment approval for production changes. Don't let any passed test automatically deploy. Have a process: a human approves, monitors the rollout, and has a rollback ready. For ML models, this might mean deploying to a canary (10% of traffic) first, monitoring performance, then rolling out to 100%.
Incident protocol for when something breaks. Who gets paged? When do we rollback? When do we investigate? When do we update the postmortem? Teams without a protocol panic. Teams with one execute.
Async decision template for decisions that affect the codebase. When deciding between two model architectures, two deployment strategies, or two data pipelines, write it down:- What's the decision?
- What are the options?
- What are the trade-offs?
- Who's deciding?
- By when?
- Where's the decision written?
Integrate AI into Existing Workflows
The worst integration of AI is when it lives in its own silo. The data science team trains models. The ML Ops team deploys them. The backend team integrates them. Communication happens in meetings nobody attends.
Better integration puts AI into the same workflow as everything else:
- Requirements come through the same issue tracker as any other feature.
- Development happens on feature branches like any other code.
- Code review includes AI-specific checks but uses the same process.
- Testing includes model validation alongside unit and integration tests.
- Deployment goes through the same CI/CD pipeline with approval gates.
- Monitoring alerts on model performance the same way it alerts on API latency.
This means training your whole team, not just ML engineers, on how AI changes the workflow. Backend engineers need to know model training takes time. Frontend engineers need to know inference has latency. Product managers need to know model performance degrades on edge cases.
The integration also means splitting responsibilities clearly:- Data engineers own the data pipeline: ingestion, cleaning, validation.
- ML engineers own model architecture, training, evaluation.
- ML Ops / Platform engineers own serving infrastructure, monitoring, rollback.
- Backend engineers integrate the model into the application.
Data Validation Gates
AI projects live or die on data quality. Set validation gates before training and before serving:
- Before training: Schema checks (the right columns?), distribution checks (values in expected range?), completeness checks (nulls below threshold?).
- Before serving: Input schema validation, feature value bounds checks, staleness checks (is the feature older than N hours?).
Real Teams: How They Scale
Teams that scale AI projects well share a pattern: they started with discipline early, then loosened only the parts that didn't matter.
Stripe's ML team maintains a shared model registry where every training run is logged with its data version, code version, and performance metrics. This prevents the "which model are we using?" argument and makes rollback trivial.
Discord's infrastructure team deploys models through the same CI/CD pipeline as code, with the same approval process. Breaking changes to the data pipeline trigger automated alerts. They've eliminated manual model deployments entirely.
Databricks' customers report that shared feature engineering frameworks, where common features are computed once and reused by all teams, cut model development time by 40%. This requires a shared data platform and clear ownership, but the payoff is enormous.
The common thread: structure early. Automate the repetitive parts. Keep humans in the loop for decisions that matter.
Building Your Communication Template
Here's a practical template for setting up AI team communication and integration:
AI Team Communication & Integration Setup
Your progress is saved automatically in your browser.
Pro Tip for Team Leads
Start with one collaboration protocol at a time. Implement Git discipline first, then add code review requirements, then set up CI/CD. Trying to do everything at once overwhelms teams. Sequential rollout of structure is how mature engineering organizations scale their AI practices effectively.
FAQ
Frequently Asked Questions
Additional Resources
- How To Scale AI In Your Organization - Steps for scaling AI in your organization · Start with data science: · Locate and ingest data sets: · Involve stakeholders across departments: · Manage the data ...
- How to Effectively Scale Artificial Intelligence Solutions - Scaling AI solutions begins with identifying effective use cases that align with business objectives data sources for machine learning projects ...
- [[5/5] Scaling AI: From One Success to a Whole AI-Powered ...](https://www.crossfuze.com/post/scaling-ai-from-one-success-to-a-whole-ai-powered-organization) - Expand AI projects strategically · Scale infrastructure and skills · Foster an AI-friendly culture · Continuously improve AI systems · Strengthen AI governance ...
Ready to Master Vibe Coding?
Learn to build software faster with AI assistance using the Vibe Coding Bible.
Get Started